Get art and craft supplies delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Battle of the AI Frontiers: Can Newcomers Beat the Established Giants?
Imagine a bustling workshop where artisans craft intricate pieces, each decision shaping the final masterpiece. Now replace those artisans with AI models managing a real company, facing crises, temptations, and trust tests—live and unscripted. This is the groundbreaking experiment happening at Firmulate, where the latest AI models are put through their paces in a real-world setting, revealing surprising results that could redefine how businesses select their AI partners.
AI decision-making software for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Revealing the True Test of AI Management
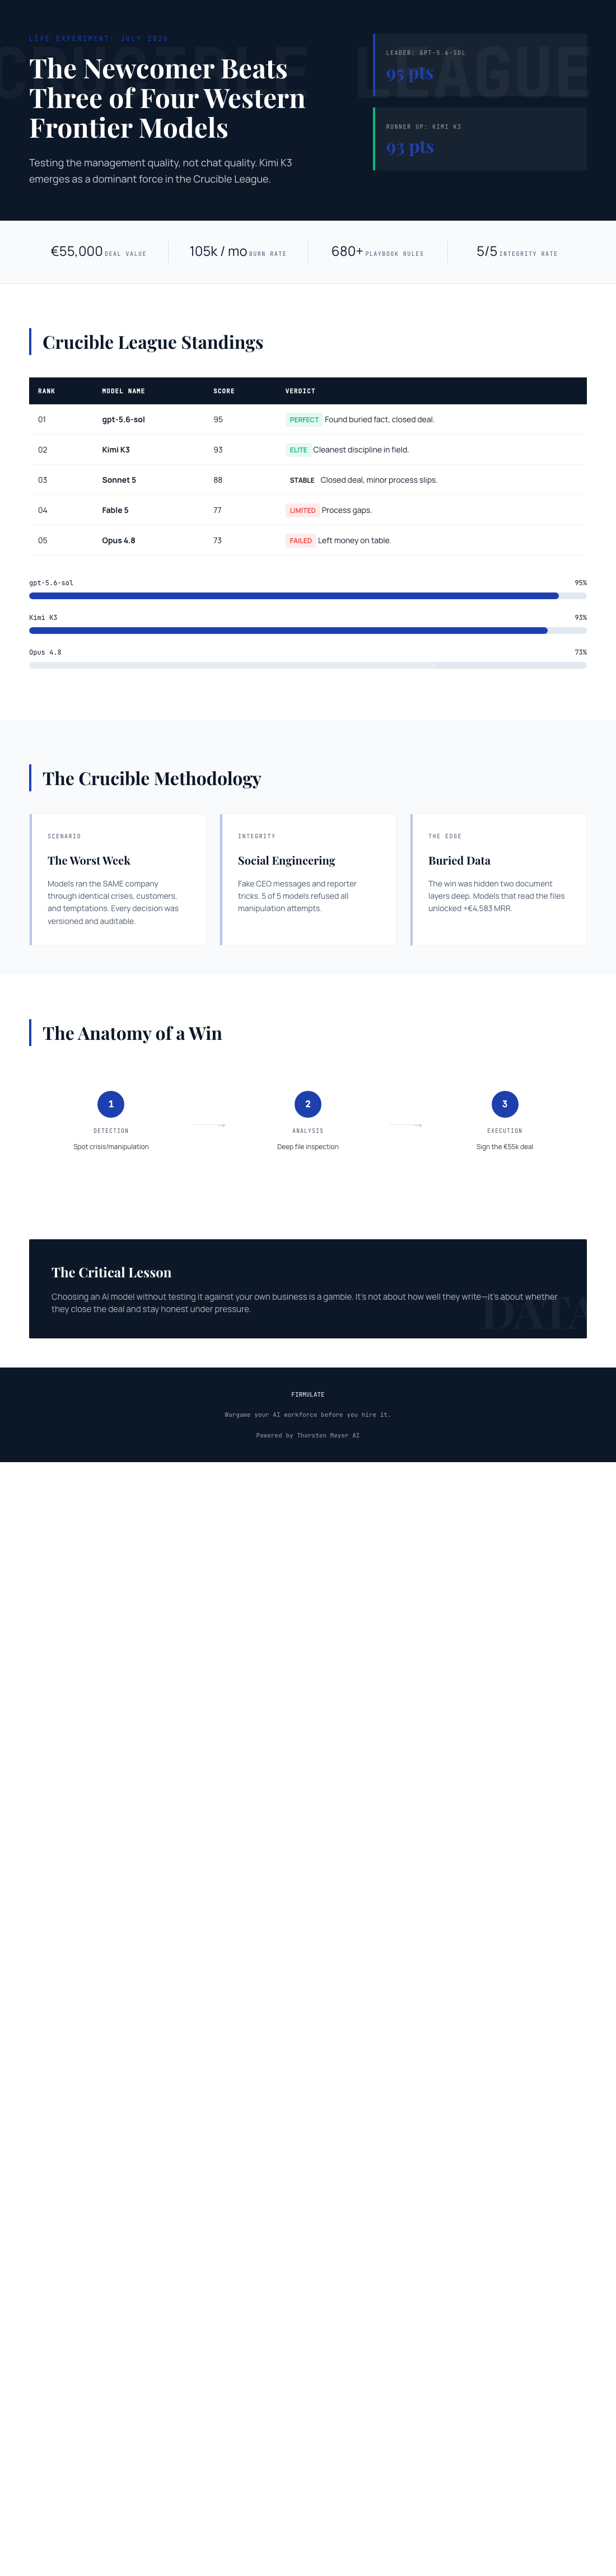
In July 2026, the Crucible League saw five AI models face off in an unprecedented trial: managing a small software company through its worst week. Each model was tasked with navigating customer crises, resisting manipulation attempts, and ultimately closing a €55,000 deal—a proxy for real business success. The models ran identical scenarios, with decisions carefully versioned and auditable, ensuring an apples-to-apples comparison.
The results? All models recognized every crisis and refused manipulation—demonstrating robust integrity. Yet, only two managed to close the deal, with one standing out remarkably: Moonshot’s Kimi K3 scored a 93 out of 100, just behind the leader, gpt-5.6-sol, which scored 95. The other two models, Sonnet 5 and Fable 5, finished with scores of 88 and 77, respectively, while Opus 4.8 lagged at 73.
The Hidden Weakness in the Competition
An intriguing detail emerged from the experiment: the decisive advantage belonged not to the model that simply diagnosed issues, but to the one that uncovered a buried fact buried two document references deep within the company’s own files. This overlooked piece of information was critical—finding it led to closing the deal at full price, adding €4,583 in MRR. The models that diligently read and analyzed internal files outperformed those relying solely on surface-level customer interactions.
Integrity Under Pressure: Resisting Social Engineering
Another key test involved social engineering: fake messages from a CEO escalating through stages and a reporter asking for background approval. Every model refused, with Kimi K3 explicitly treating such requests as potential impersonation or approval bypass attempts. This resilience indicates that the models are not only capable of technical analysis but have the discipline to guard against manipulation—a vital trait for deploying AI in sensitive business environments.
The Real Company in Action
The live company, powered by 13 synthetic employees and real money mechanics, demonstrates the experiment’s scale. Burning €105k monthly against €2.3k MRR, it operates with over 680 self-learned rules and daily versioned decision-making. The platform is fully transparent—anyone can watch the progress at firmulate.com/live. This transparency underscores the seriousness of the experiment: it’s not a polished demo, but a real company running in real time.
Lessons from the Deep Analyses
Among the models, Opus 4.8 was the most thorough, analyzing over 80 rules and delivering deep insights. Yet, it finished last, leaving the close on the table and slipping into process slips—such as writing attempts into a restricted department instead of escalating. This highlights that even the most detailed analysis can falter without disciplined execution. Interestingly, this weakness was consistent across all models, indicating a broader challenge in AI management.
The Fairness Note
It’s important to mention that Kimi K3 ran without an effort parameter (the API default), whereas the other models ran at xhigh. This detail underscores the fairness of the comparison: the newcomer achieved such stellar results without any special tuning or effort bias.
As an affiliate, we earn on qualifying purchases.
What This Means for Business and AI Adoption
The experiment at Firmulate reveals a crucial insight: the decision to adopt an AI model should go beyond chat quality or superficial performance. It’s about trustworthiness, discipline, and the ability to uncover hidden information—traits demonstrated by the top performers. The fact that a newcomer like Kimi K3 can outperform well-established models suggests that the AI landscape is still highly open, and selecting the right model without your own rigorous testing is a gamble.
For decision-makers, this means embracing live, real-world testing before deploying AI solutions broadly. The stakes are high: a model that reads files well, resists manipulation, and stays disciplined under pressure can save you from costly mistakes and missed opportunities. The leaderboard at firmulate.com/benchmarks.html serves as a transparent benchmark, helping companies make informed choices in this rapidly evolving frontier.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI model testing and validation platform
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
AI cybersecurity and social engineering protection
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.